Riskiest Assumption Test (RAT)
What it is, how to find the assumption worth testing, and why the test comes before the MVP — not instead of it.
How to run a riskiest assumption test
The test itself is the easy part. The work is choosing which assumption deserves it — most teams test the belief that is easiest to test, not the one that would sink them.
- 1
List the assumptions
Write down every belief the idea depends on, as “We believe that…”. Cover all four kinds: will they want it, can they use it, can we build it, does it work for the business.
- 2
Map them by impact × evidence
For each one, ask how much damage it does if it is wrong (impact) and how much you actually know (evidence). High impact with little evidence is the riskiest corner.
- 3
Pick the riskiest
Choose the assumption that would most change your plan if it turned out false. Usually one, at most two or three.
- 4
Design the smallest test, and set the bar first
Pick the cheapest experiment that gives a clear signal (a fake door, five interviews, a look at the data) and write down what result would count before you run it.
- 5
Run it, and record what you learned
Mark the assumption validated or invalidated, keep the evidence with it, and move to the next riskiest — or build, if the linchpin held.
For the mapping in depth, see the assumption testing and mapping guide; for what a good riskiest assumption looks like, the 16 examples by type; and for choosing the test, the ten product experiments.
Where each idea comes from
The MVP was popularized by Eric Ries in The Lean Startup: the version of a new product that generates the most validated learning for the least effort. The intent was always learning — but in practice the term inflated. "MVP" came to mean "version one with fewer features": still weeks of building, still a launch, still a roadmap defending it.
The riskiest assumption test was Rik Higham's 2015 reaction to that inflation ("The MVP is dead. Long live the RAT."): don't build the smallest product — build the smallest thing that tests your riskiest assumption. Usually that isn't a product. It's a fake door, five interviews, a landing page, or a two-day spike.
The distinction matters because an MVP tests everything at once. When it flops — most do — you can't tell which belief killed it: nobody wanted it, nobody understood it, or nobody would pay. A RAT isolates the one belief that decides whether the rest is worth testing at all.
RAT vs MVP, side by side
It's a sequence, not a rivalry
Take a concrete bet: a weekly activity digest to reduce churn. The MVP-first path builds the digest — templates, scheduling, unsubscribe handling — and learns four weeks later that admins don't open it. The RAT-first path asks: what does this bet most depend on? That busy admins want a weekly digest at all. Test it with a fake "Weekly digest" toggle in settings; success criterion: at least 20% of active admins opt in within two weeks. Two days, one clear signal.
If the toggle stays untouched, you just saved a month — and you know precisely why: desirability failed, not your copywriting or your cron jobs. If it clears the bar, you build the MVP knowing the demand is real, and the next riskiest assumption ("a digest actually changes behaviour, not just opens") becomes the thing the MVP measures.
When to skip the RAT and just build
Honesty clause: testing everything is its own failure mode. Skip the ceremony when:
If support tickets, interviews, or analytics already answer the question, running a test is procrastination. Attach the evidence to the assumption and move on.
If building the thing costs a day and reversing it costs nothing, the build is the test. Ship it behind a flag and watch what happens.
Feasibility assumptions are often tested by building — a spike is a RAT that happens to be code. The trick is timeboxing it and throwing it away.
The reverse trap is more common: calling a six-week build "an experiment." If it has a backlog, a launch date, and no pre-written success criterion, it's not a test — it's a bet you've stopped questioning.
Find your riskiest assumption as a team
Picking the riskiest assumption alone is easy and usually wrong: you test what you already doubt, and the belief everyone takes for granted never gets questioned. The assumption workshop in Outcomify runs the mapping with your whole team in about 40 minutes. Right-click an opportunity or a solution on your tree and choose Run assumption workshop.
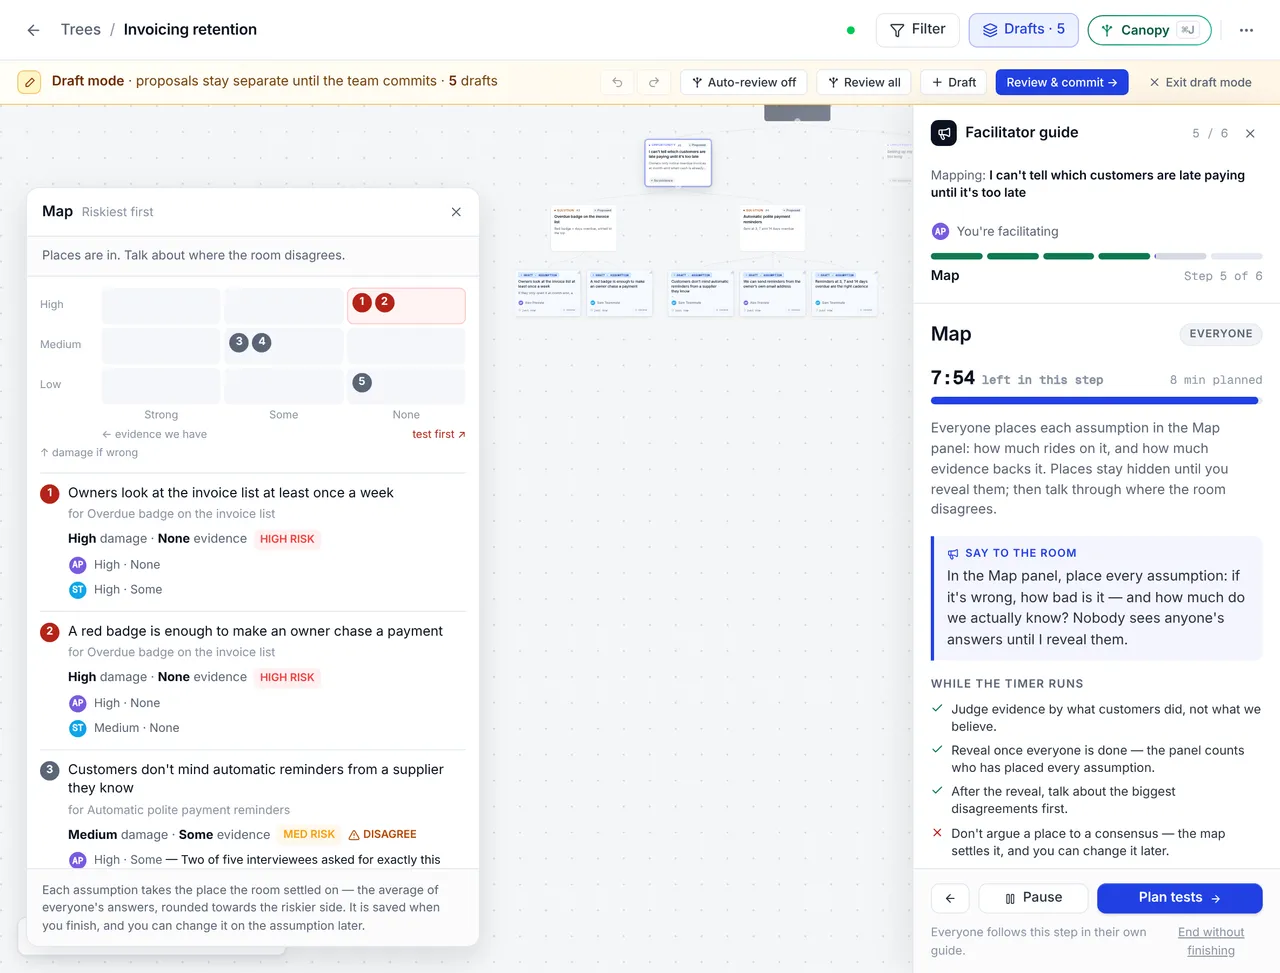
Everyone writes assumptions on their own, then places each one on impact × evidence without seeing anyone else's answer. Nobody anchors on the loudest voice.
The facilitator reveals the map. Each assumption settles where the room put it, the riskiest come first, and the ones you disagreed on are flagged to talk through.
Plan a test with a success bar for the top two or three. Finishing puts the assumptions and their tests on your tree, with a risk badge from where they landed.
Frequently Asked Questions
Common questions about riskiest assumption tests and MVPs
Keep exploring
A/B test sample size calculator
Free: how many visitors a test needs, and how many days your traffic takes to get there.
Assumption Testing & Mapping
The full method: surface, map by impact × evidence, and test the riskiest first.
Product Experiments
Ten ways to test an assumption, and which doubt each one answers.
Riskiest Assumption Examples
Concrete examples by type — each with the smallest test and a success criterion.
What is an Opportunity Solution Tree?
The framework where assumptions hang under the solutions that depend on them.
Test the belief before you build the product
Map your assumptions with your team, test the riskiest first, and keep the results on your Opportunity Solution Tree — so everyone knows what's been tested and what's still faith.